01Synthetic Data & Model Collapse
Watch at 0:45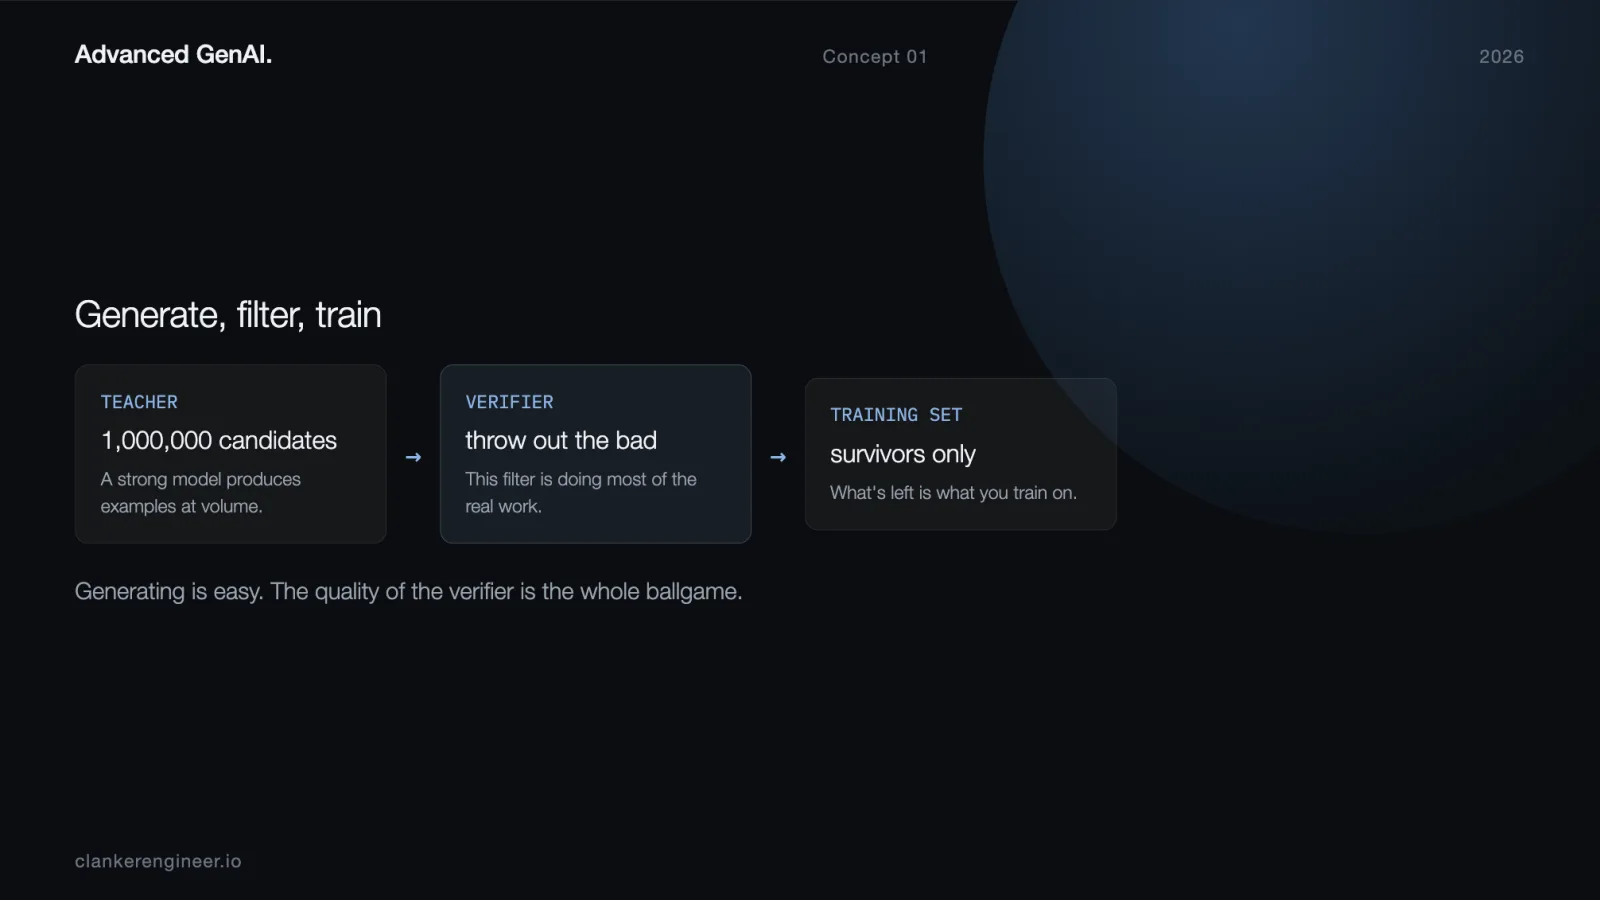
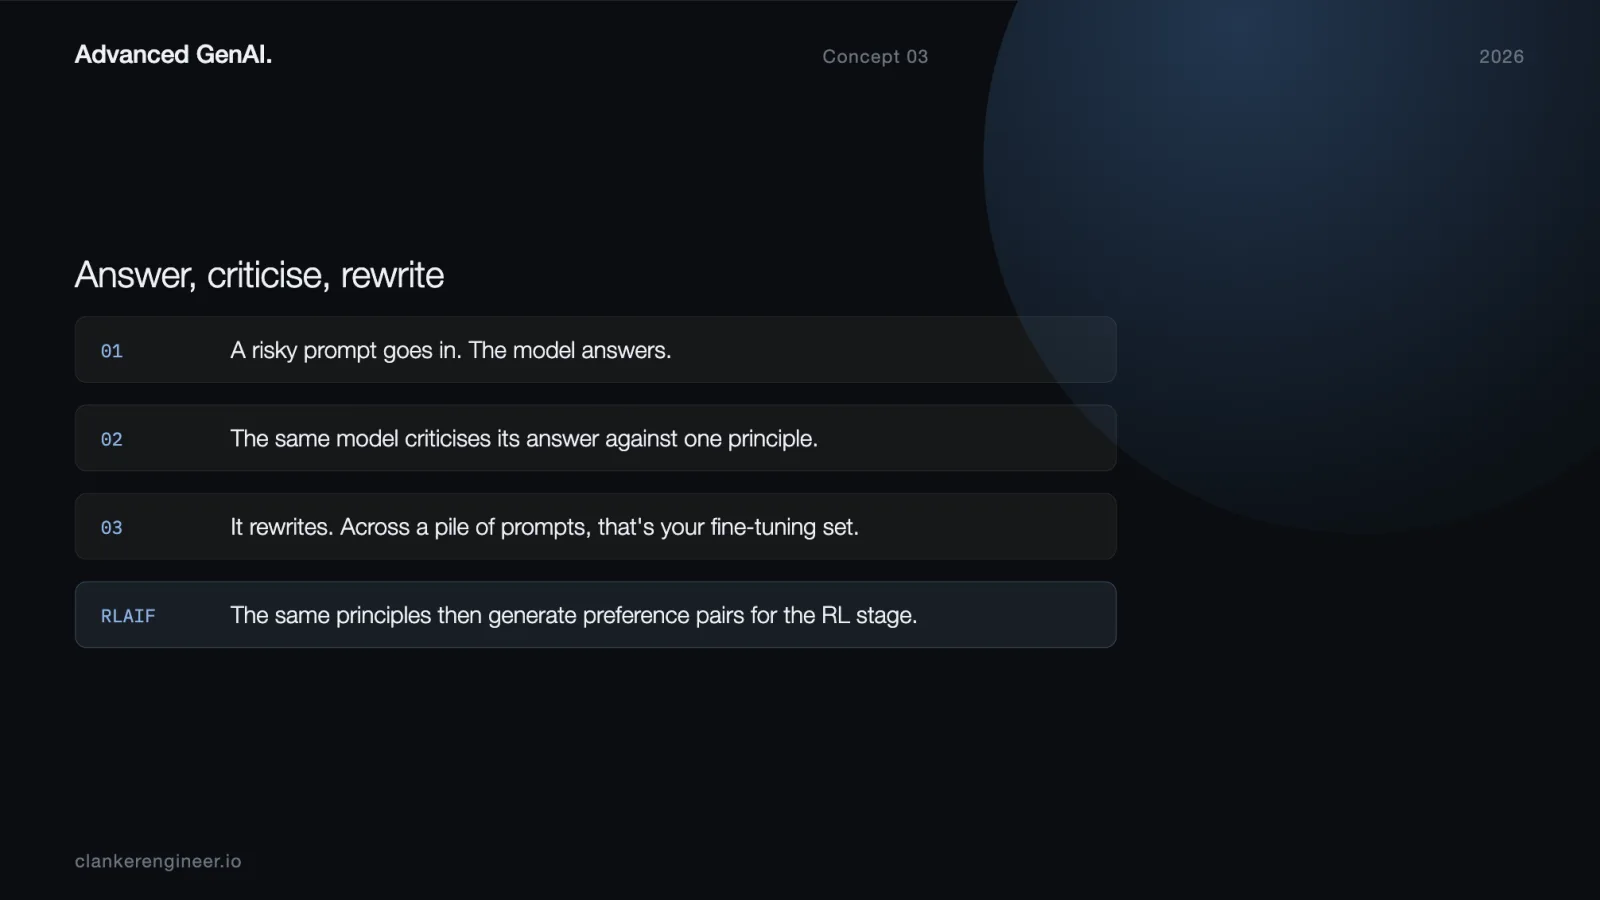
Synthetic data is training data generated by a model instead of collected from real people or real events.
You point a strong model at a task, have it produce examples by the million, throw out the bad ones, and train on what survives.
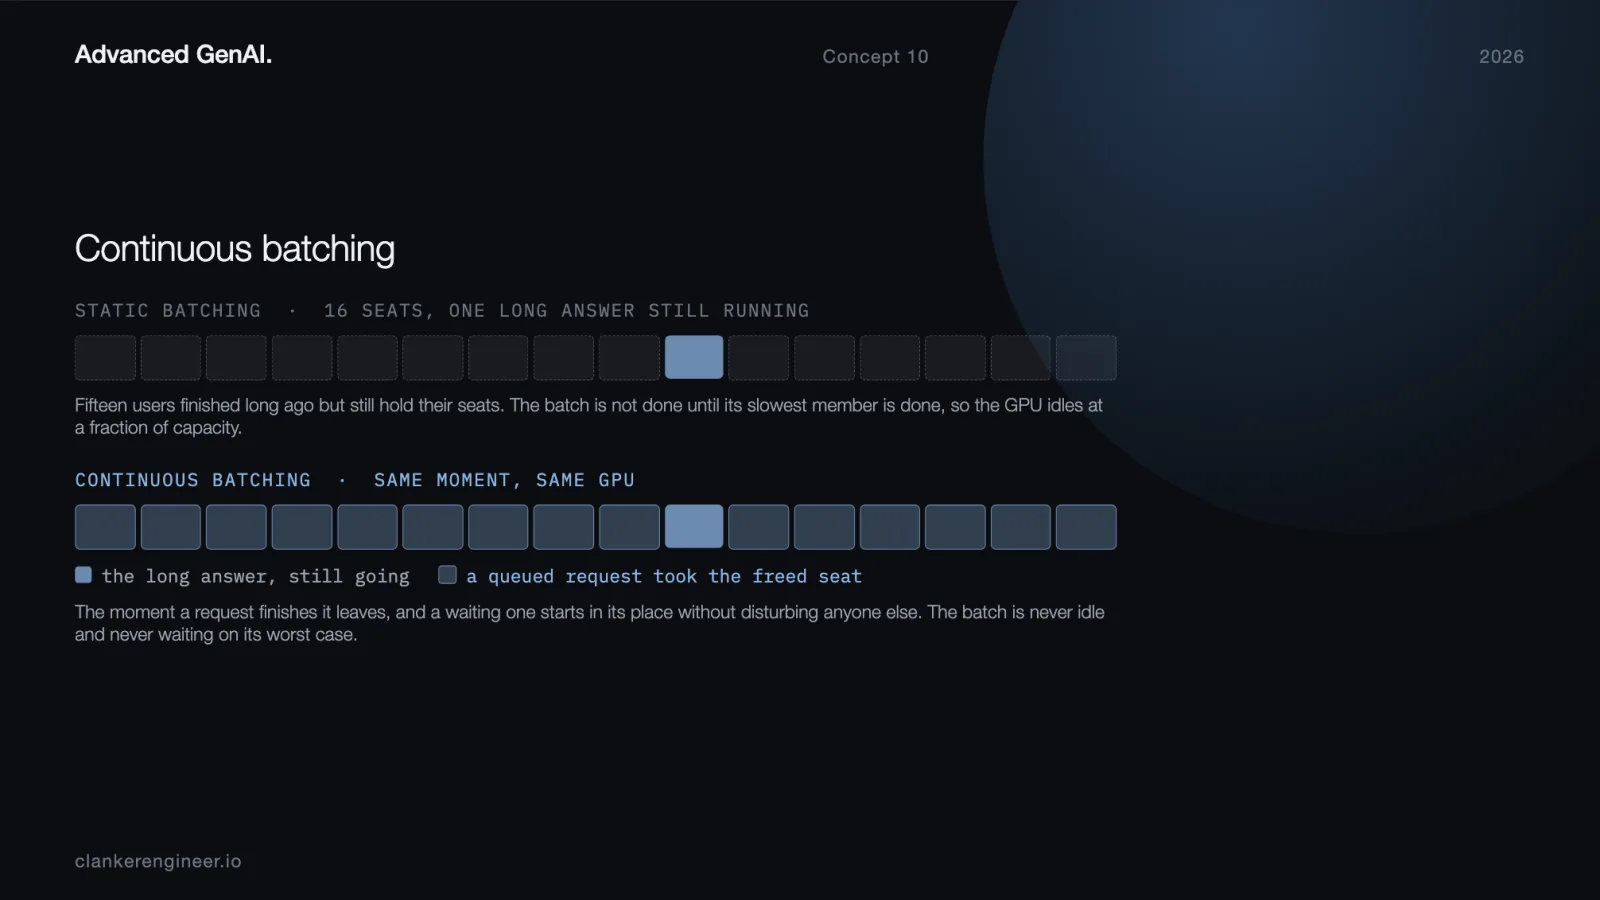
Why it matters: the internet is finite, and most of the good data is already used up by today's models. If you need a million examples of some narrow format, nobody has collected that for you.
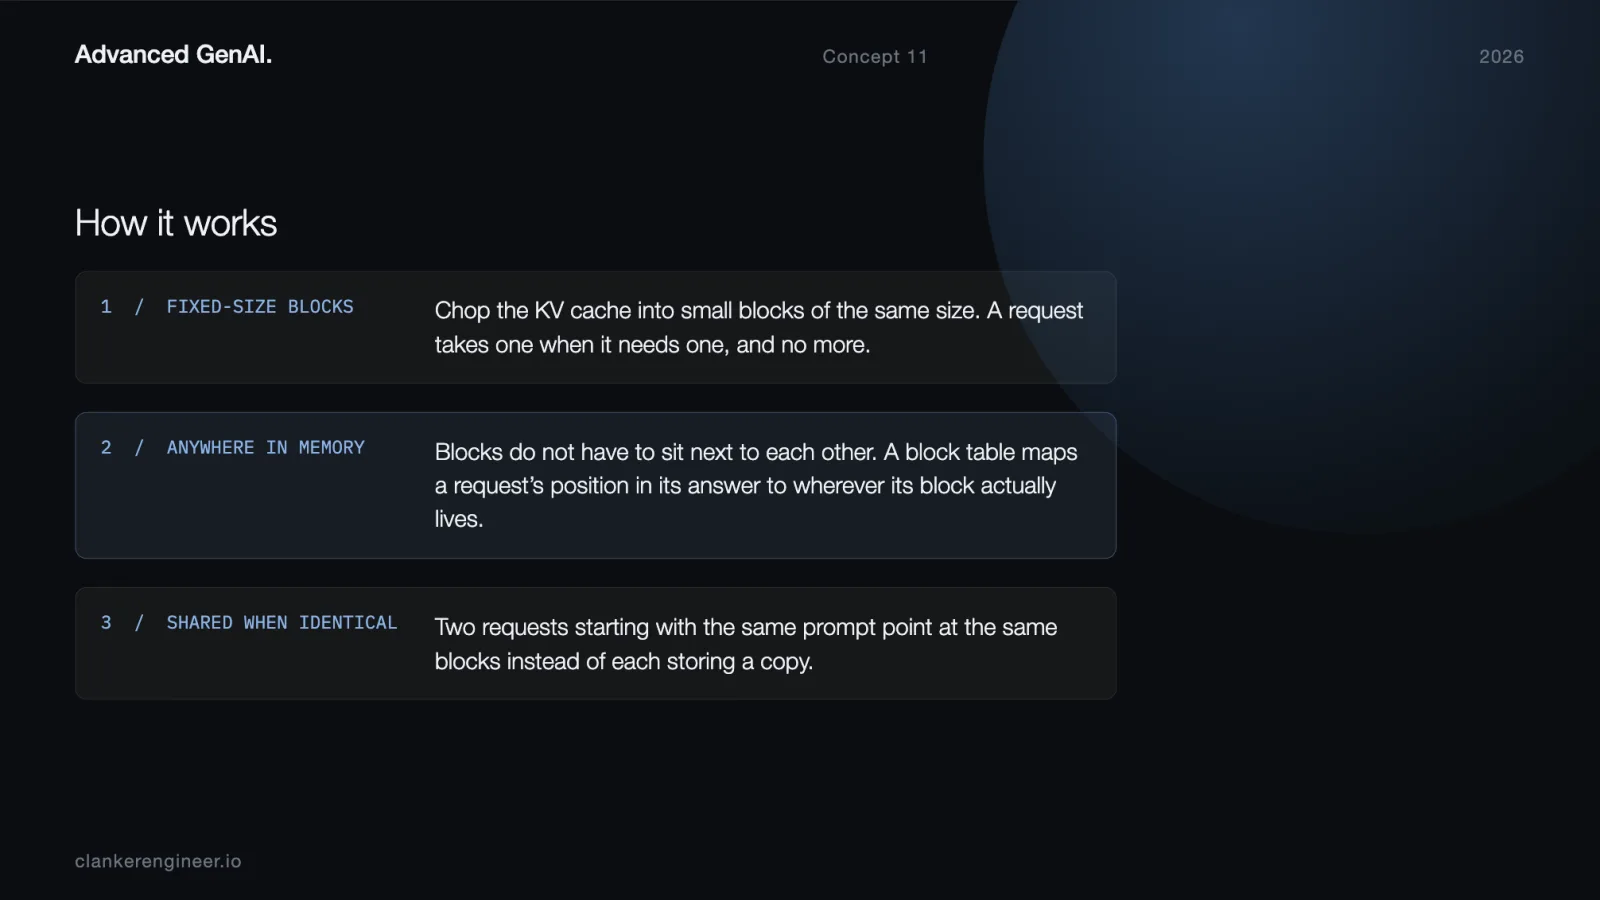
How it works:
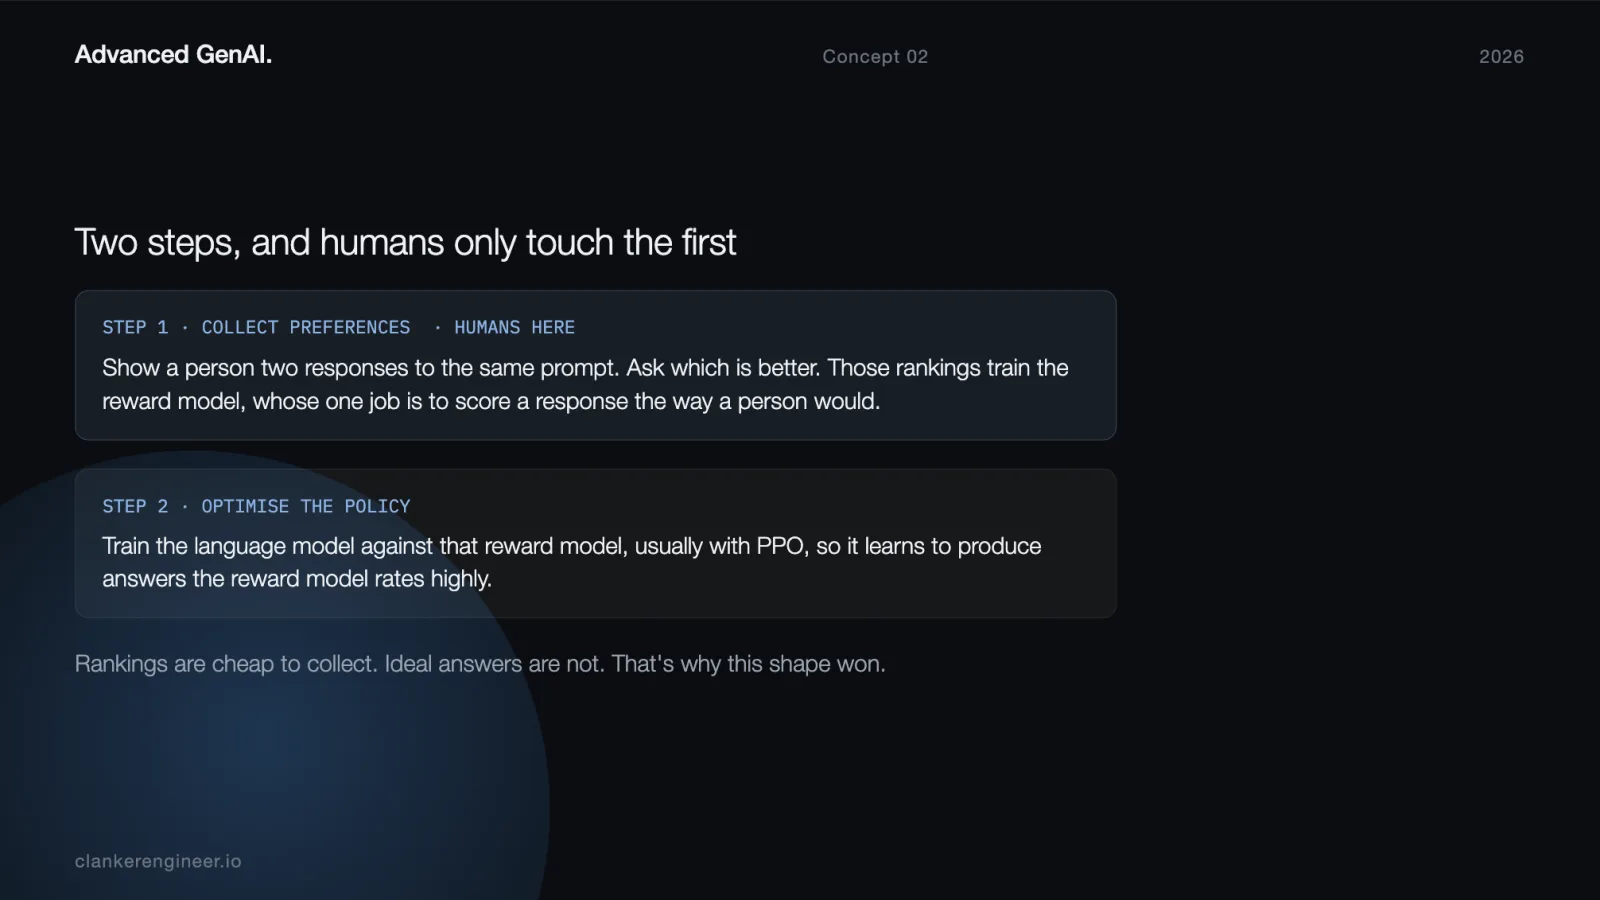
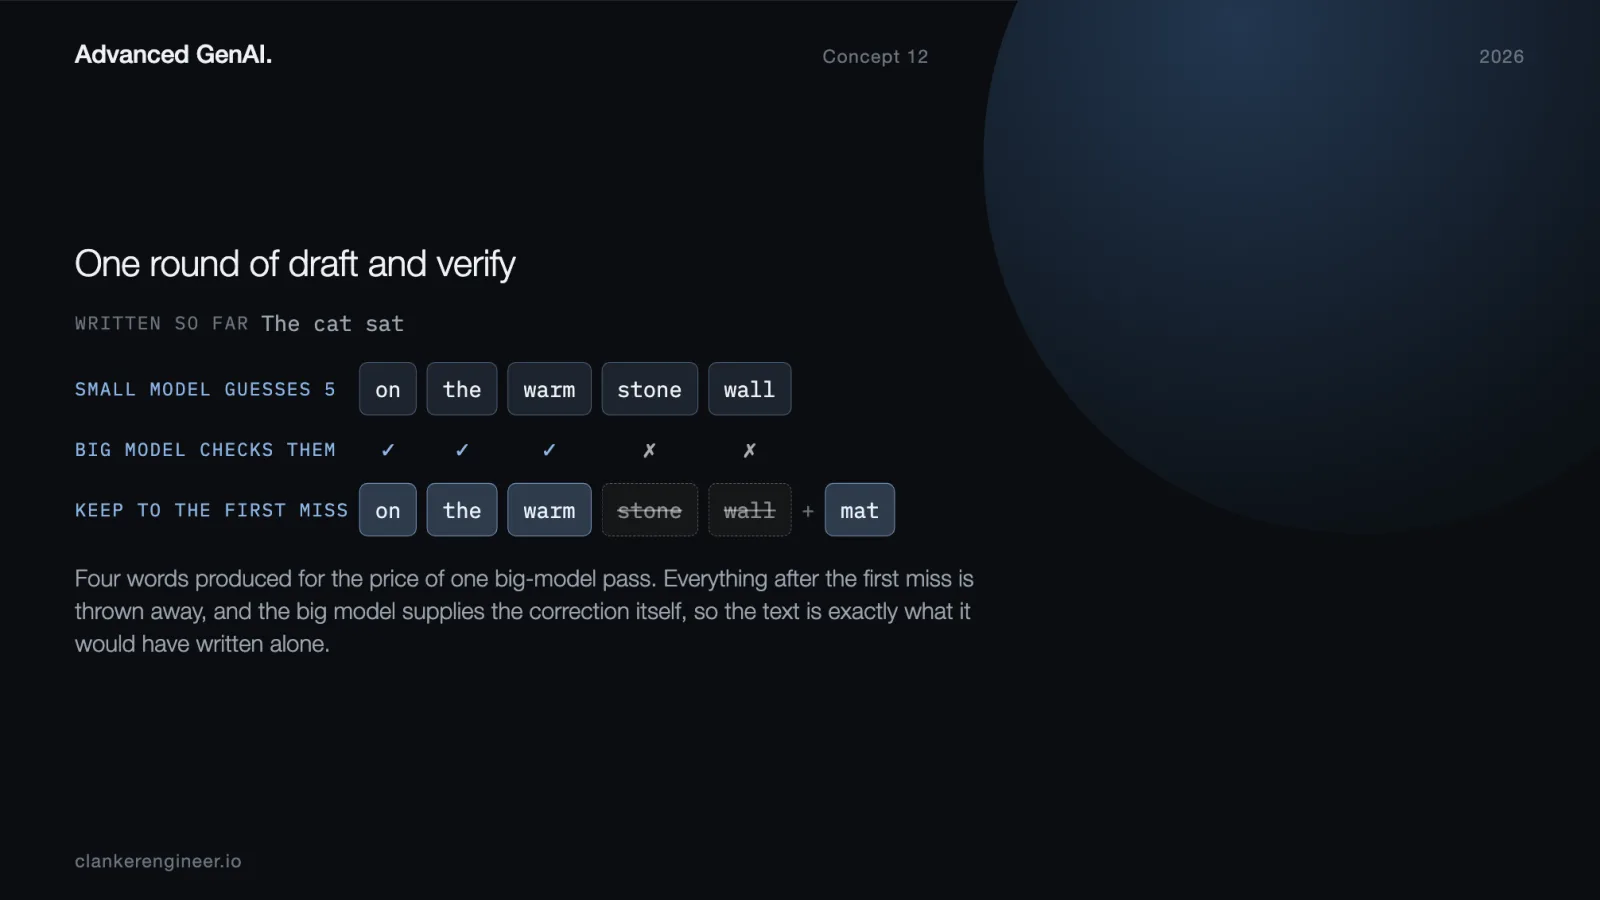
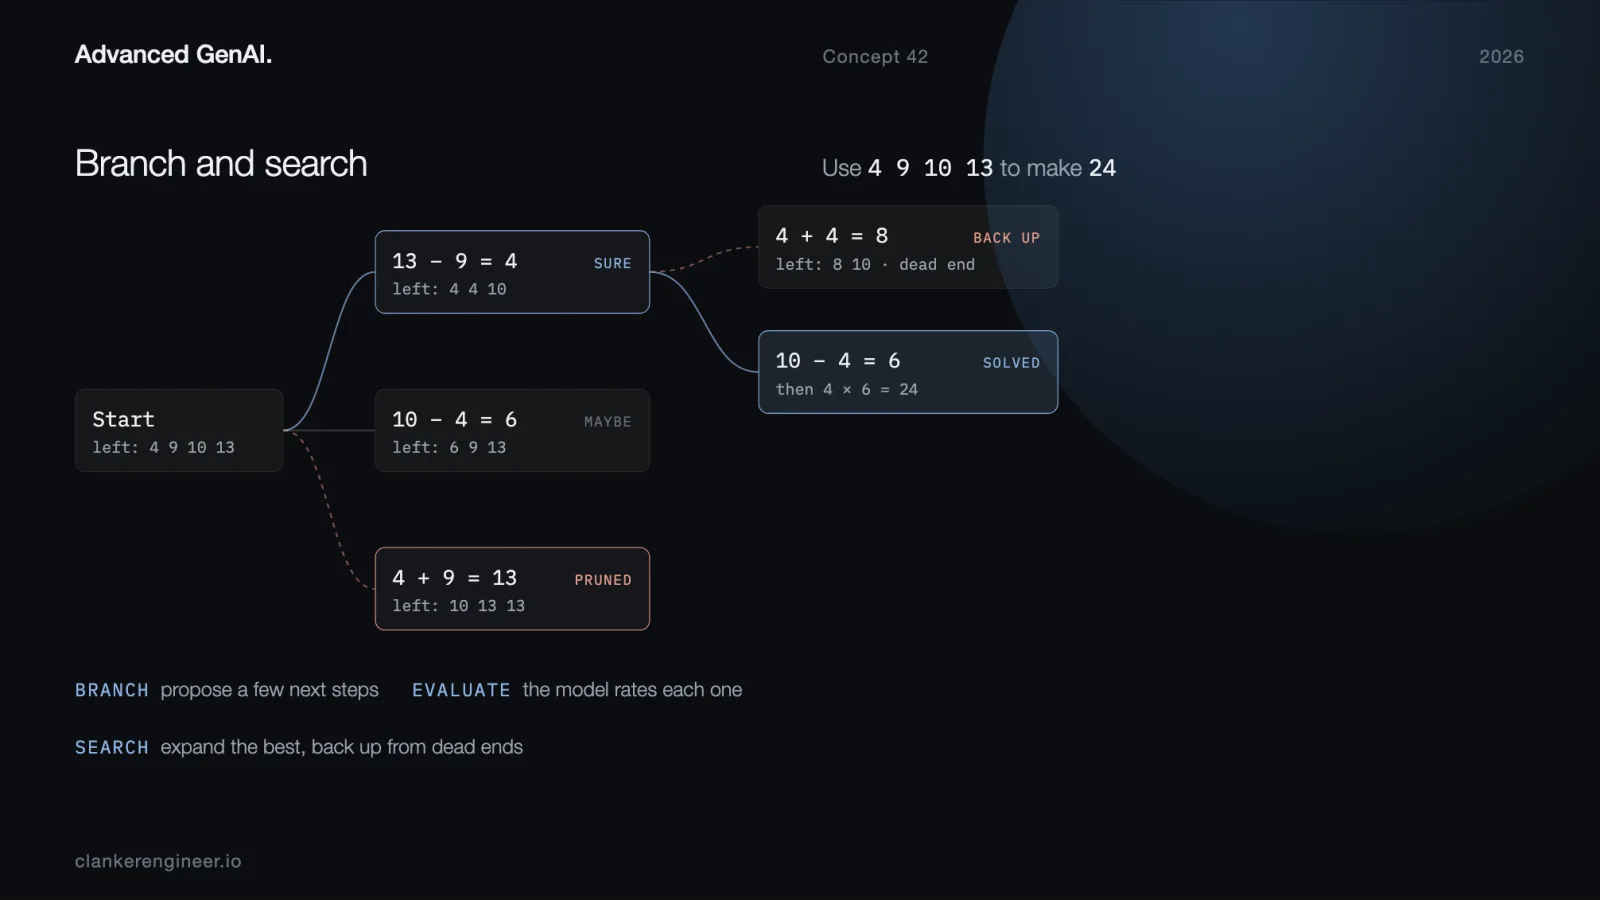
- A teacher model generates candidates
- A verifier scores them and throws out the bad ones
- Only the survivors reach the training set
That filter is doing most of the real work.
The trade-off: model collapse. Train a model on its own unfiltered output for long enough and it drifts toward its own average, smoothing away the rare cases you cared about.
So use synthetic data where the answer can be checked automatically:
- Code that has to run and return the expected output
- Math where the equation has to balance
And never train on synthetic data alone. Keep real data in the mix.